Skip to content

Lasting Effects of Abstract Pretraining Beyond Perplexity

Sep 2026 · 0 citations · 38 references
Computer Science

Abstract

Language models are typically pretrained from random initialization. Recent work challenges this convention, showing that a brief warm-up on abstract, algorithmically generated data can provide a better starting point for subsequent learning of natural language. In this paper, we show that in small language models, such a warm-up improves specific capabilities that are not reflected in language-modeling perplexity. Our warm-up uses an abstract stack-manipulation task that requires compositional and state-tracking capabilities. Allocating as little as 1% of pretraining tokens to this data improves multi-hop question answering by up to 3.9 F1 points on MUSIQUE, with additional gains on HOTPOTQA and 2WIKIMULTIHOPQA despite comparable language-modeling perplexity. Controlled experiments show that the warm-up substantially accelerates the acquisition of deeper reasoning chains. We also explore what drives this transfer. First, the structure of the data matters: replacing the stack task with a queue fails to produce the same gains. Second, the gains are specific: performance improves on sequential reasoning chains, with no consistent benefit on tasks that combine or compare independent facts. Third, timing matters: mixing abstract data with natural language is far less effective than an initial dedicated phase, and exposure after pretraining completely removes the benefits. The early advantage persists through billions of subsequent language tokens. These results show that early abstract training can reliably shape the capabilities language models later acquire.
View source

Similar papers

#machine learning Review Open access Oct 2014

Software development in startup companies: A systematic mapping study

The results indicate that software engineering work practices are chosen opportunistically, adapted and configured to provide value under the constrains imposed by the startup context.

Nicolò Paternoster, Carmine Giardino, M. Unterkalmsteiner et al. · 394 citations · ⚡54

Diffusion models as plug-and-play priors

The possibility of inferring high-dimensional data inference in a model that consists of a prior and an auxiliary differentiable constraint given some additional information is considered, thereby allowing a range of potential applications in adapting models to new domains and tasks.

Alexandros Graikos, Esmeralda S. Whitammer, N. Jojic et al. · 316 citations · ⚡15

Trajectory Balance: Improved Credit Assignment in GFlowNets

It is proved that any global minimizer of the trajectory balance objective can define a policy that samples exactly from the target distribution, and empirically demonstrate the benefits of the trajectories balance objective for GFlowNet convergence, diversity of generated samples, and robustness to long action sequenc...

Esmeralda S. Whitammer, Moksh Jain, Emmanuel Bengio et al. · 302 citations · ⚡60
#computer vision Open access Jun 2016

Software Development in Startup Companies: The Greenfield Startup Model

The results are packaged in the Greenfield Startup Model (GSM), which explains the priority of startups to release the product as quickly as possible, and the need to shorten time-to-market, by speeding up the development through low-precision engineering activities.

Carmine Giardino, Nicolò Paternoster, M. Unterkalmsteiner et al. · 178 citations · ⚡14
#machine learning Review Open access Jun 2014

Why Early-Stage Software Startups Fail: A Behavioral Framework

This state-of-practice investigation was performed using a literature review followed by a multiple-case study approach and presents how inconsistency between managerial strategies and execution can lead to failure by means of a behavioral framework.

Carmine Giardino, Xiaofeng Wang, P. Abrahamsson · 175 citations · ⚡19
#computer vision Open access Oct 2016

Software Startups - A Research Agenda

Software startup companies develop innovative, software-intensive products within limited timeframes and with few resources, searching for sustainable and scalable business models.

M. Unterkalmsteiner, P. Abrahamsson, Xiaofeng Wang et al. · 157 citations · ⚡17

Related blog posts

GPT-Lab Sep 3, 2026

Adaptive AI Agents in Construction Workflows

Adaptive AI agents can help make BIM data more machine-readable by navigating IFC models, interpreting inconsistent information, and mapping it to defined standards. In this blog, Alok Rawat shares findings from a real-world pilot in construction workflows. The post Adaptive AI Agents in Construction Workflows appeared first on GPT-Lab.

GPT-Lab Aug 28, 2026

We built an AI factory for HVAC control

What does it take to trust AI-driven HVAC optimization? Our AI Model Factory combines agents, machine learning, reinforcement learning and deterministic checks in a governed workflow designed for messy, real-world building data. The post We built an AI factory for HVAC control appeared first on GPT-Lab.

Microsoft Research Blog Jul 30, 2026

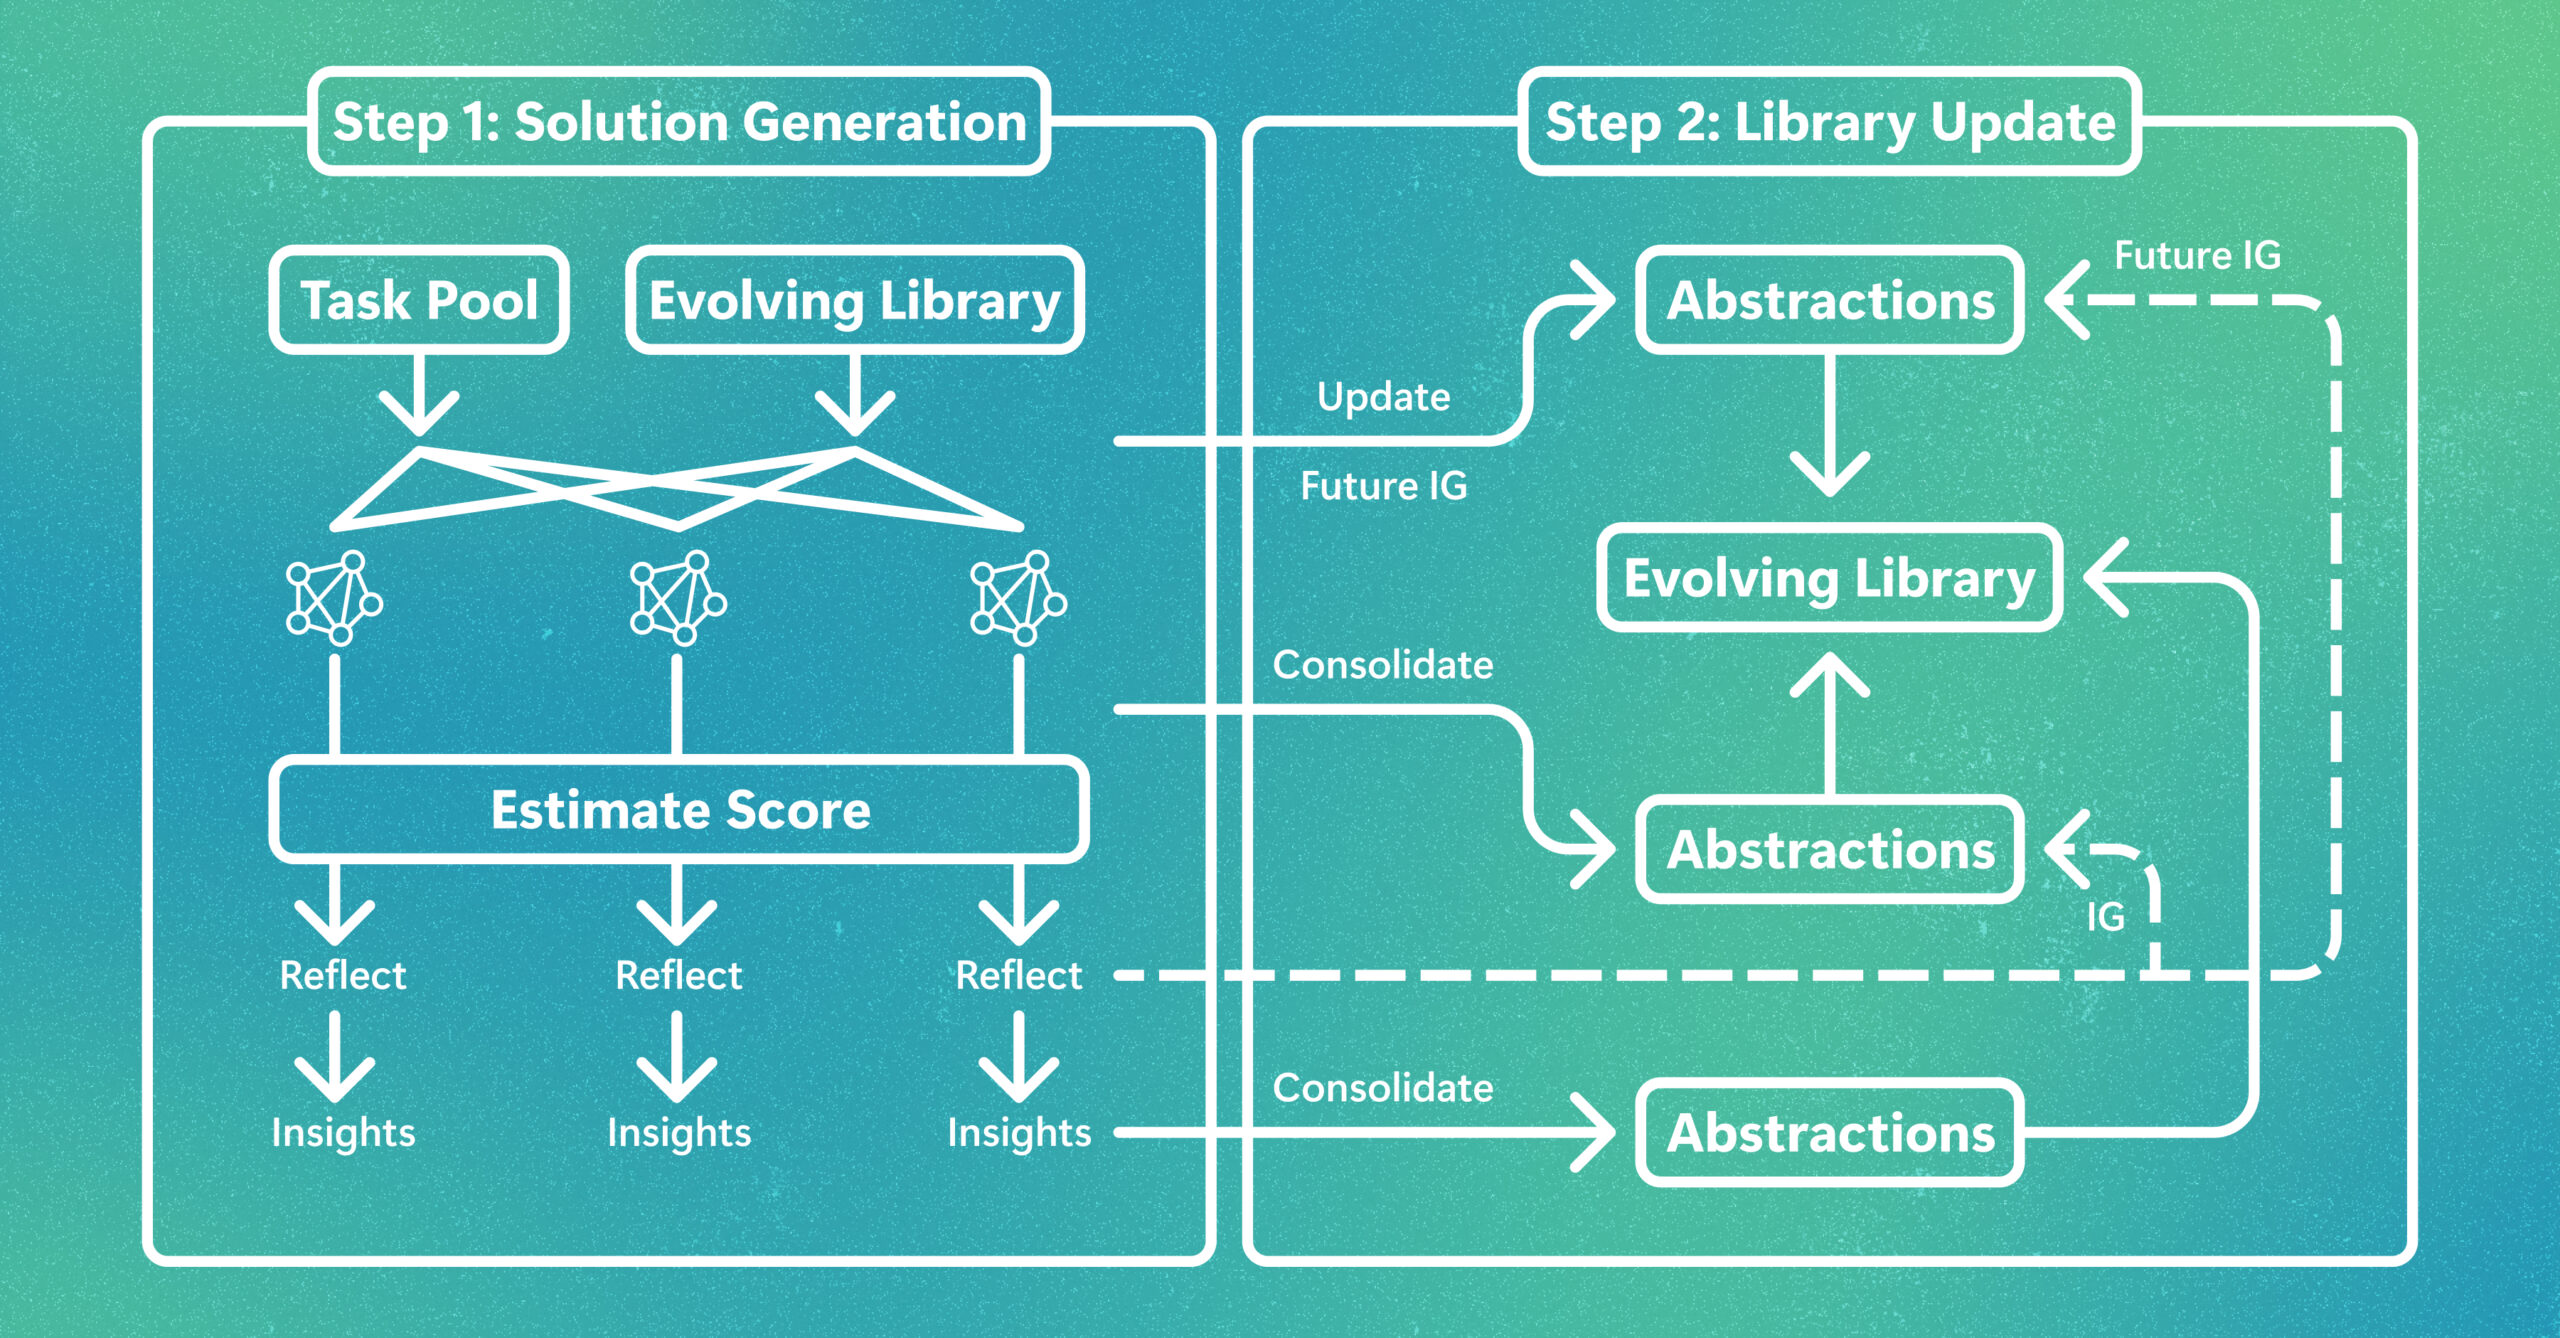
EvoLib: Turning experience into evolving knowledge

LLMs do not get smarter just by remembering more. EvoLib turns experience into evolving knowledge, taking reusable skills and insights that help models learn and adapt across tasks long after deployment. The post EvoLib: Turning experience into evolving knowledge appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.