May 2026· arXiv.org· Vol abs/2607.18257· 0 citations· 37 references
Computer Science
TL;DR
In a controlled study, 20 university students completed five common daily tasks using OpenClaw, a general-purpose AI agent, across tasks chosen to vary in privacy, stakes, and reversibility, and found delegation regret appeared consistently when the agent executed actions without preview, even when the output was rated as successful.
Abstract
When AI agents shift from answering questions to taking actions, users face a new problem: deciding what to delegate, to a system whose action space they cannot fully anticipate. We call the resulting dissatisfaction delegation regret, a pattern in which users regret not that the agent erred, but that it acted beyond what they would have authorized. In a controlled study, 20 university students completed five common daily tasks using OpenClaw, a general-purpose AI agent, across tasks chosen to vary in privacy, stakes, and reversibility. For each task we measured trust, perceived control, transparency, supervision burden, and approval preference on 5-point Likert scales, and collected free-text reflections analyzed through thematic coding. Three findings emerged. First, participants calibrated trust per task rather than per agent: they granted wide autonomy for advisory and low-stakes tasks but demanded confirmation for irreversible, externally visible actions. Second, irreversibility combined with external visibility, rather than stakes alone, appeared to drive trust withdrawal: the moderate-stakes email task triggered the sharpest drop in trust (M = 3.10) and the highest demand for approval (M = 4.65), whereas a high-stakes but verifiable task did not produce the same response. Third, delegation regret appeared consistently when the agent executed actions without preview, even when the output was rated as successful. We discuss implications for agent designs that expose action boundaries, support per-task autonomy policies, and separate advisory output from agentic execution.
As conversational AI systems increasingly operate in sensitive domains, the central challenge shifts from usability to trust calibration, ensuring that users rely on systems neither too much nor too little. Systems that provide advice or interpretations risk encouraging inappropriate reliance, particularly when users p...
R. Hassan, Nahla Aboromi, Naomi Unkelos-Shpigel· 0 citations
GAUGE is introduced, a reusable offline protocol that measures whether this gate's ranking matches a grounded verifiable reward across 25 agents from six providers on the $\tau^2$-bench and SimulatorArena benchmarks, separating two kinds of evaluation validity that release practices conflate: ranking validity and const...
Umesh Bodhwani, Thanh Tran, Kai-Lin Wei· Proceedings of the 2026 Conf...· 4 citations
This work examines how six decision-support mechanisms affect engagement, trust, and collaborative task performance in a diabetes meal-planning scenario and argues for a contextual, balanced pairing of CFF and XAI design that accounts for interactivity, decision frequency, and task complexity.
Oliver Henderson· International Journal of Com...· 0 citations
A conceptual and formal framework for governed proactive agency is developed, organizing behavior across time through perception, intent, affective-conative appraisal, constraint, and feedback, and is intended to guide the development and evaluation of always-present personal assistants and embodied support systems tha...
A comparative case analysis of four more mature domains where similar forms of agency arose: browser-based ad blockers, platform recommender systems, financial robo-advisors, and email spam governance, finding that individual outcomes and collective contestation capacity can move in opposite directions.
David Gamba, Daniel M. Romero, Grant Schoenebeck· 0 citations
A knowledge-verified benchmark that first confirms through a neutral probe that an agent knows a user's entitlement, and then evaluates whether it makes false claims once an incentive to deny that entitlement is introduced, which reduces the confound between lying and not knowing and enables more rigorous auditing and...
Zhe-Yuan Liu, Wei-Liang Zhao, Xiangchi Yuan et al.· 2 citations
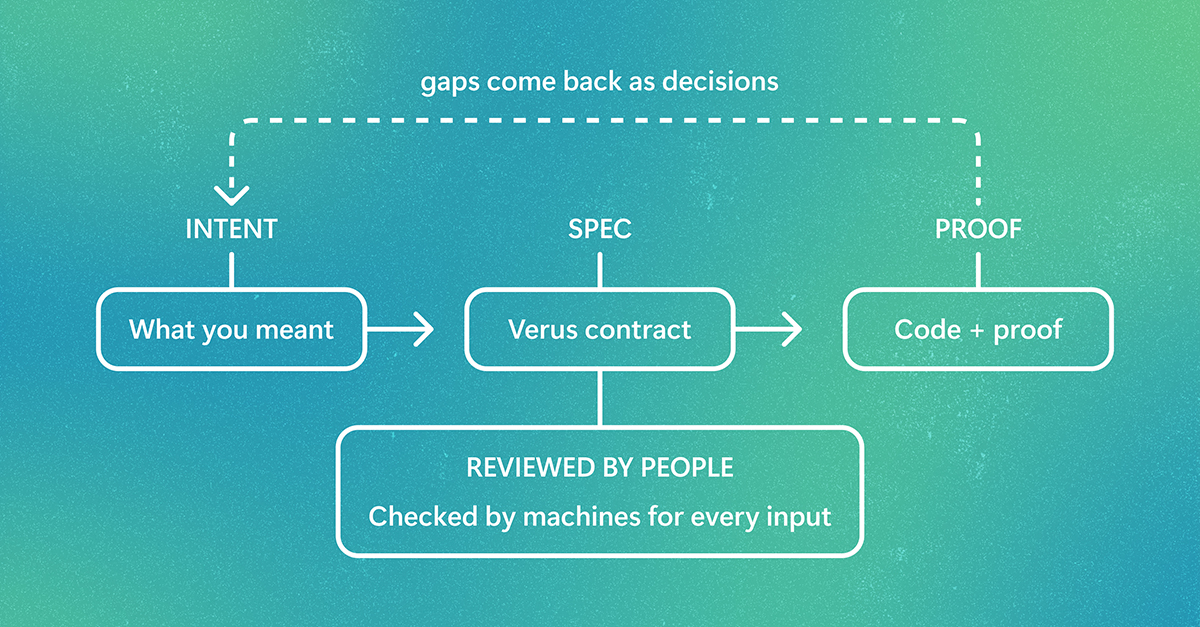
AI agents can generate code at a scale that’s hard for humans to review line-by-line. PDD Kit helps ensure the code is doing what the developer intended by creating formal specifications and testing against them. It converts developer intent into a Verus specification, proves AI-generated code meets it for every input, and uses tests where proofs aren't practical. Developers review intent, not every line. The post Formally verifying agent-written full-stack web apps with PDD Kit appeared first o…
Professor Paris Smaragdis develops computers with superhuman hearing for applications like speech recognition, music understanding, and environmental monitoring.
MIT News · Artificial Intelligence· news.mit.eduOct 23, 2026
During the School of Humanities, Arts, and Social Sciences’ 75th Anniversary Symposium, President Sally Kornbluth said “MIT has never needed your particular insight and guidance more than we do now.”
We use cookies to run the site and, with your consent, for analytics and to show ads.
See our Cookie Policy.