Skip to content

Dual Graph Network Hashing for Cross-Modal Retrieval

Sep 2026 · IEEE Transactions on Knowledge and Data Engineering · Vol 38, pp. 5781-5797 · 0 citations · 64 references

Abstract

Hashing algorithms represent data by generating compact binary hash codes, enabling efficient cross-modal similarity search and significantly improving the storage efficiency and retrieval performance of image-text data. However, because traditional hashing methods typically separate image-text feature extraction from hash learning, the feature extraction module struggles to adaptively update based on training feedback, further limiting the performance of cross-modal retrieval in real-world scenarios. To address this issue, deep learning has been introduced to cross-modal hashing, enabling end-to-end joint optimization and tightly integrating feature extraction and hash learning, significantly improving retrieval performance. However, because existing deep learning methods often use a fixed weight distribution when processing samples, they ignore the modal differences between text and visual features when fusing them. This leads to an inadequate fused representation and difficulty achieving optimal modality alignment during hash code generation. To address this issue, we propose a Dual Graph Network Hashing (DGNH) algorithm that dynamically adjusts the weight distribution between visual and text features through an adaptive attention mechanism, ensuring better modality fusion during hash code generation. Specifically, we design a novel framework that combines a graph convolutional neural network (GCN) with a graph attention network (GAT) to construct a label classifier for generating labels and enhancing cross-modal feature representation. This approach improves feature discrimination by capturing the hierarchical relationships and co-occurrence patterns of labels through a carefully constructed label association graph. Furthermore, we introduced a pre-trained model combining CLIP and the Transformer to further enhance the overall feature representation. During the optimization phase, we employed a contrastive triplet loss function coupled with novel regularization constraints for quantization and optimization, thus effectively reducing information loss during discretization and ensuring the generated hash codes are more compact and efficient. Experimental results on three public datasets, MS-COCO, NUS-WIDE, and MIRFlickr-25 K, demonstrate that the proposed method outperforms existing methods in both retrieval accuracy and efficiency, thereby validating its effectiveness and superiority.
View source

Similar papers

Open access Aug 2026

Unsupervised Cross-Modal Hashing Algorithms for Web Multimedia Retrieval

With the Web witnessing a rapid surge in multimodal data, it’s becoming increasingly vital to develop efficient and budget-friendly cross-modal (CM) retrieval techniques to elevate the user experience in Web applications. Traditional hashing methods, however, often neglect the valuable semantic information hidden withi...

Yang-Hao Li, Zhao-jie Dong, Shi-Song Wu et al. · 0 citations
Conference Open access Sep 2026

Retrieval-Guided Completion Hashing with Token–Patch Alignment for Incomplete Cross-Modal Retrieval

Cross-modal hashing has been extensively adopted in cross-modal retrieval tasks owing to its high storage efficiency and fast retrieval capability. However, in practical applications, multimodal data often suffer from modality missing issues, which cause semantic incompleteness and thus severely impair both cross-modal...

Zhi-Xin Luo, Zhen-Qiu Shu · 0 citations
Open access Sep 2026

Attention-enhanced vision transformer hashing for hybrid image retrieval

Large-scale image retrieval requires compact representations without substantially sacrificing retrieval accuracy. However, Vision Transformer Hashing (VTS) concatenates all output tokens before hash projection, resulting in a high-dimensional hashing head with considerable model and memory overhead. We replace this to...

Uyen Nguyen, Hoai Ba, Quynh Dao Thi Thuy · 0 citations
Aug 2026

Shared Latent Characteristic Anchored Hash Codes Generation for Efficient Fine-Grained Image Retrieval.

Hashing-based fine-grained image retrieval (FGIR) is a promising solution for large-scale domain-specific data retrieval, yet it faces a fundamental contradiction between discriminative feature learning and compact binary codes generation. Existing methods often rely on complex feature extraction modules to improve fin...

Zhen-Duo Chen, Li-Jun Zhao, Yongxin Wang et al. · 0 citations

Related blog posts

Microsoft Research Blog Jul 13, 2026

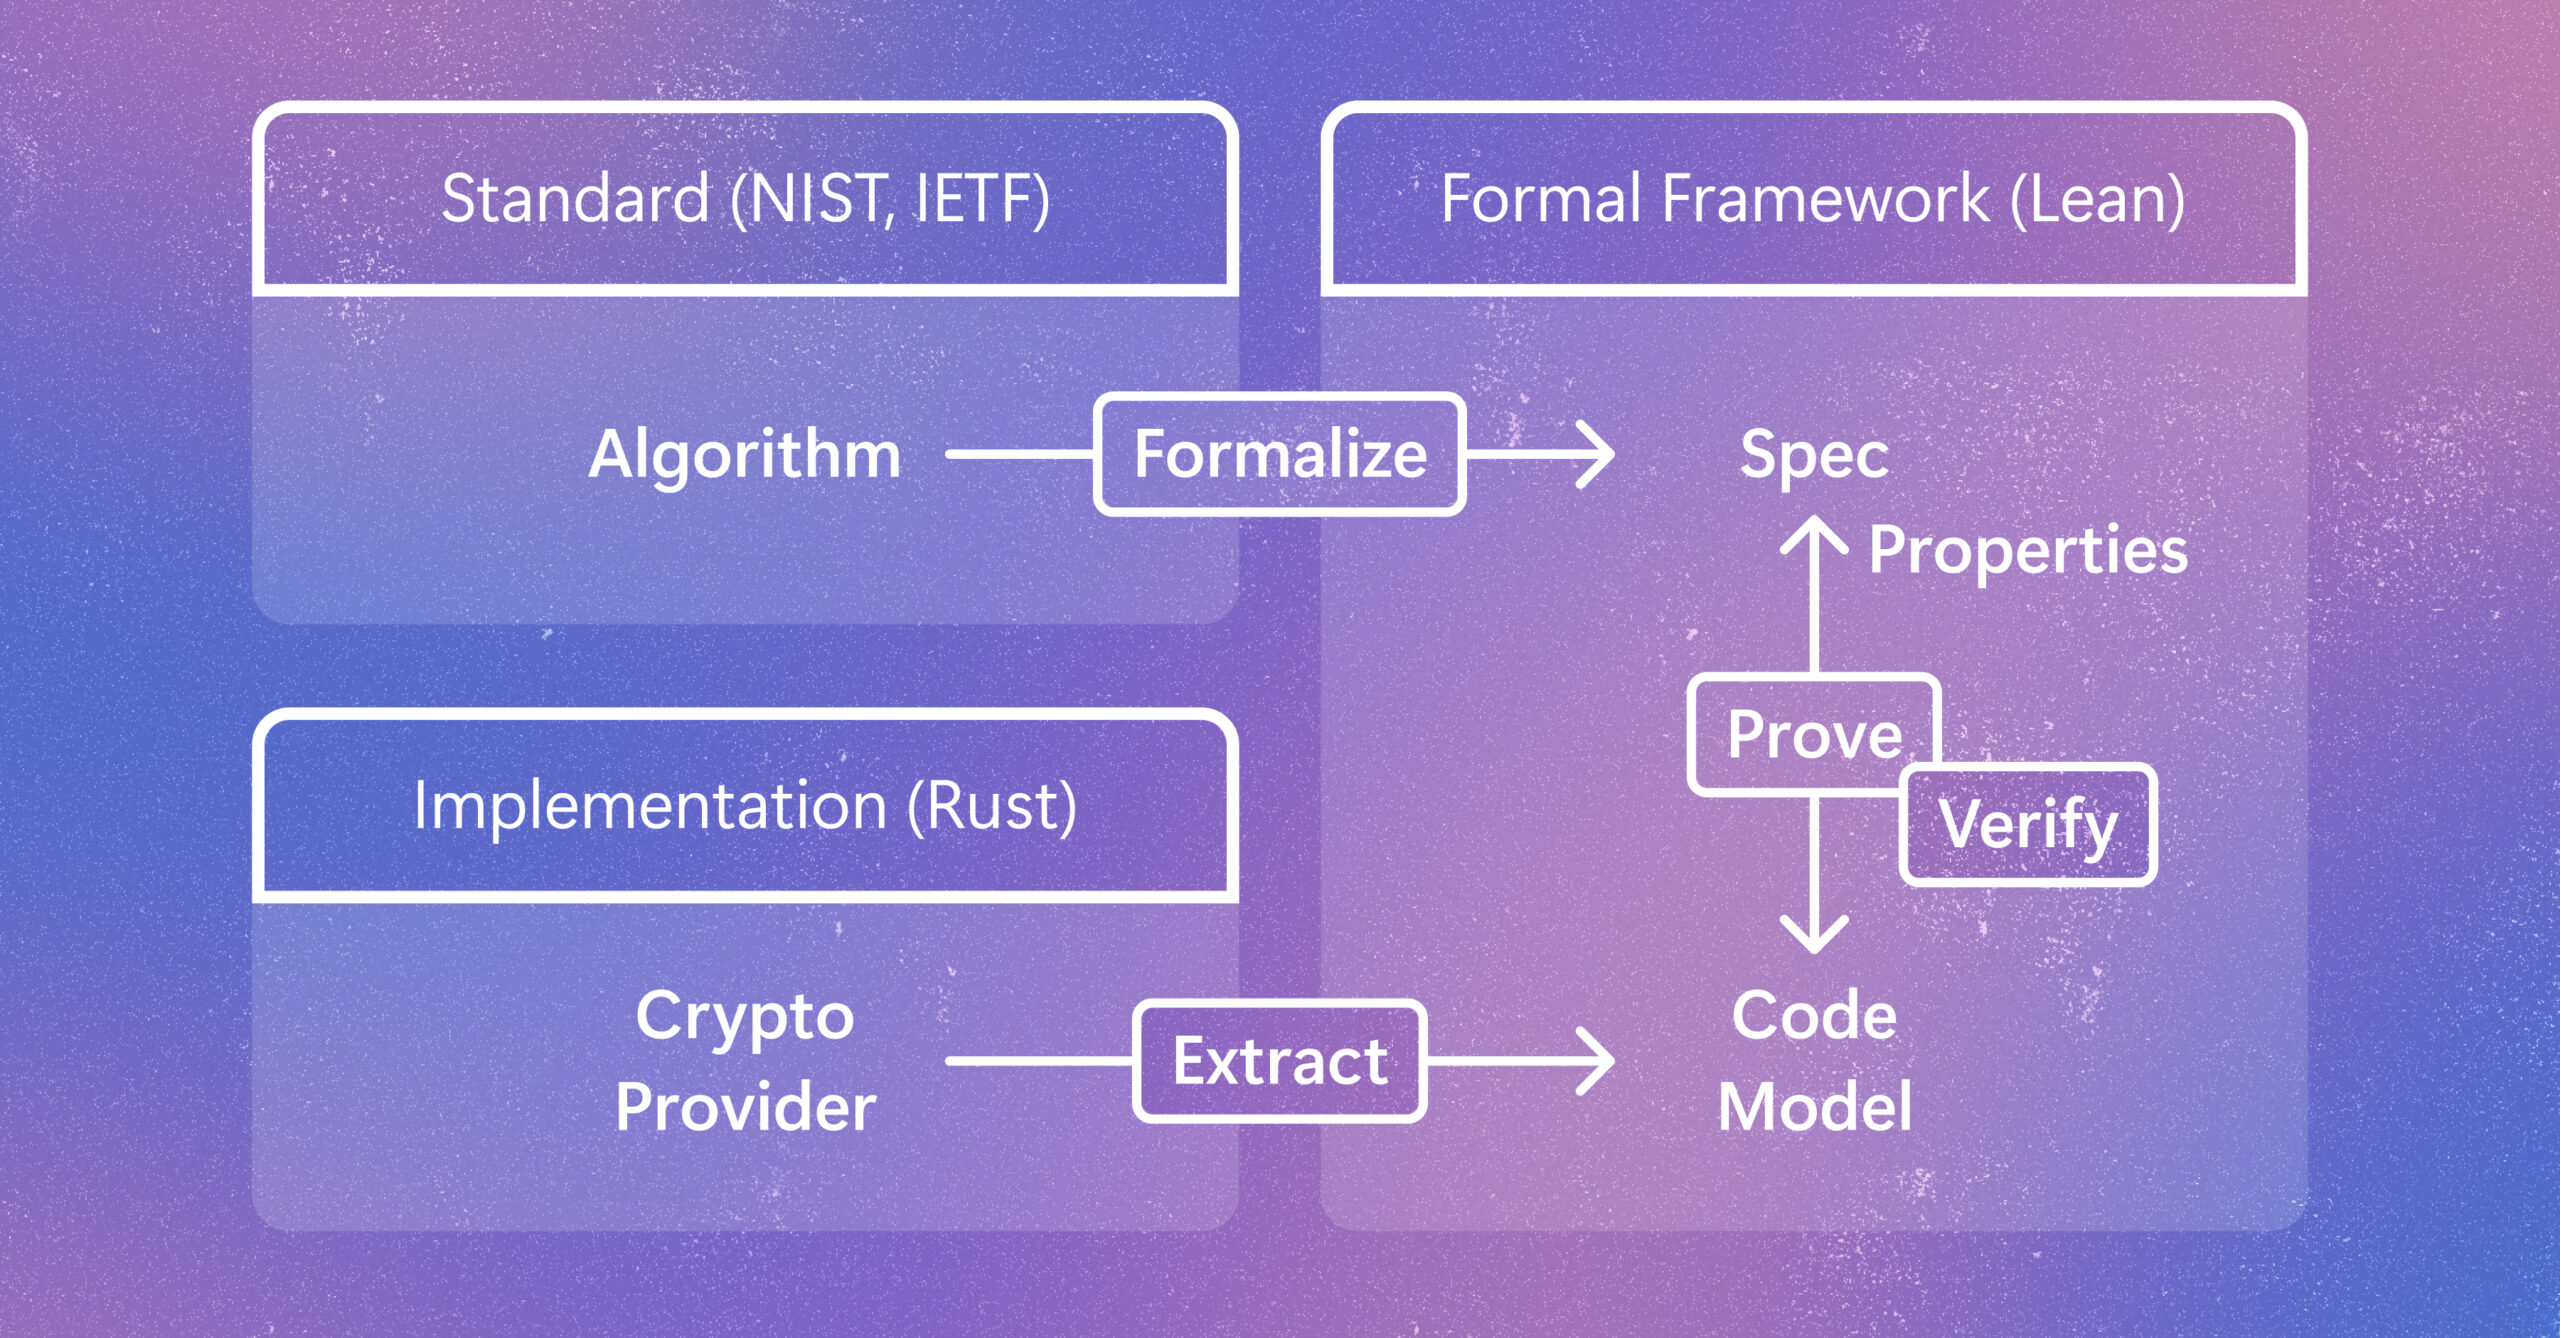
Verifying Rust cryptography in SymCrypt, from standards to code

Cryptographic code supports vital protections in modern computing systems. Learn how a new method helps verify code as developers write it while preserving speed and adaptability as it gets implemented and evolves. The post Verifying Rust cryptography in SymCrypt, from standards to code appeared first on Microsoft Research.

We use cookies to run the site and, with your consent, for analytics and to show ads. See our Cookie Policy.